Give Altera a reliable way to know whether their AI-powered product classification is actually improving, not just whether it feels like it is.
Obstacle
Every change to the matching prompts or models needed to be tested against a fixed, human-labelled standard.
Outcome
An independent evaluation framework that turns every prompt or model change into a comparable, version-controlled number.
Background
Altera is a non-profit accelerating the protein shift in European food retail, helping supermarkets measure and rebalance their sales from animal-based proteins toward plant-based and alternative options. Their platform classifies retail products and fills in missing nutrition data from the NEVO database, giving retailers the evidence they need to track protein transition commitments. With interest from retailers across Europe and real deployments approaching, Altera needed to know their classification engine could be trusted before it scaled.
Challenges
Grading Its Own Homework: The matching system’s only quality signal was the LLM’s own confidence score. There was no independent check against known correct answers, so nobody could say with certainty whether the system was accurate, let alone improving.
A Moving Target: The test dataset used to sanity-check changes was itself generated by an LLM and regenerated on most prompt iterations. That meant one run could never be fairly compared to the run before it, because the ground it was tested against had shifted underneath it. Past evaluation runs weren’t stored anywhere that supported comparison. Every question that mattered, “did this prompt change help?”, “is the confidence score trustworthy?”, “where are we still getting it wrong?”, was unanswerable with evidence.
Solution
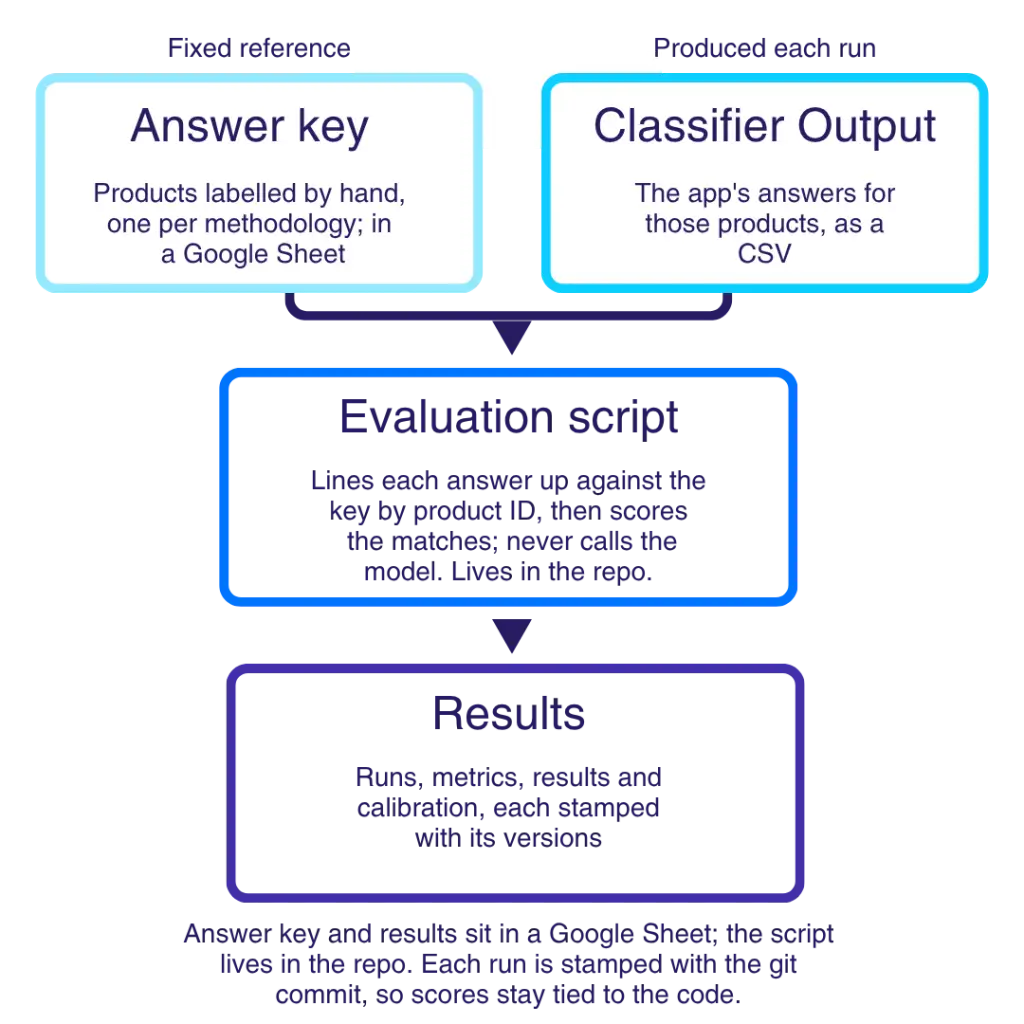
Three Test Sets, Deliberately Made Hard: For each of the three ways the app classifies products, we built a set of example products where we already knew the correct answer. Each set was checked against firm rules: no overlap with the reference set the app matches against, real retailer products rather than LLM-generated ones, and answers set by a person, not a model, so the evaluation measures whether the app is right, not whether it agrees with another AI.
A Scoring Layer That Never Touches Production: The evaluation reads the classifier’s existing output, lines it up against the golden dataset and scores it, without re-running or modifying the classification pipeline itself. Every run produces accuracy, precision, recall and a calibration check on how much the LLM’s confidence score can actually be trusted, broken down by matching category. Every run is stamped with the prompt version, model and dataset it used.
Impact
From A Guess To A Number: Altera can now answer the exact questions that were previously unanswerable: is a prompt change actually working, or did it just look different? For the first time, every change to the classification system produces a comparable score instead of a hopeful assumption.
A Safety Net Under Every Future Change: Every run is now stamped and version-controlled, so regressions get caught before they reach retailers, not after. Altera’s team can iterate on prompts and models with actual confidence, rather than crossing their fingers each time something changes.
Proof, Not Just Progress: The evaluation now runs against real, unmodified classifier output across all three workflows using hard, human-labelled test cases the app has never seen. Giving Altera confidence in how its product is performing.
Creating Value For Altera...
3golden datasets built,
3matching workflows independently verified,
And 0 changes required to the production pipeline.